Third Yandex data-center outage in four days exposes AI infrastructure risk
A drone attack shut Yandex's Vladimir data center after earlier strikes disrupted sites in Sasovo and Kaluga. The sequence has pushed parts of Yandex Cloud into emergency operation and turned physical resilience into an immediate AI-infrastructure question.
The story
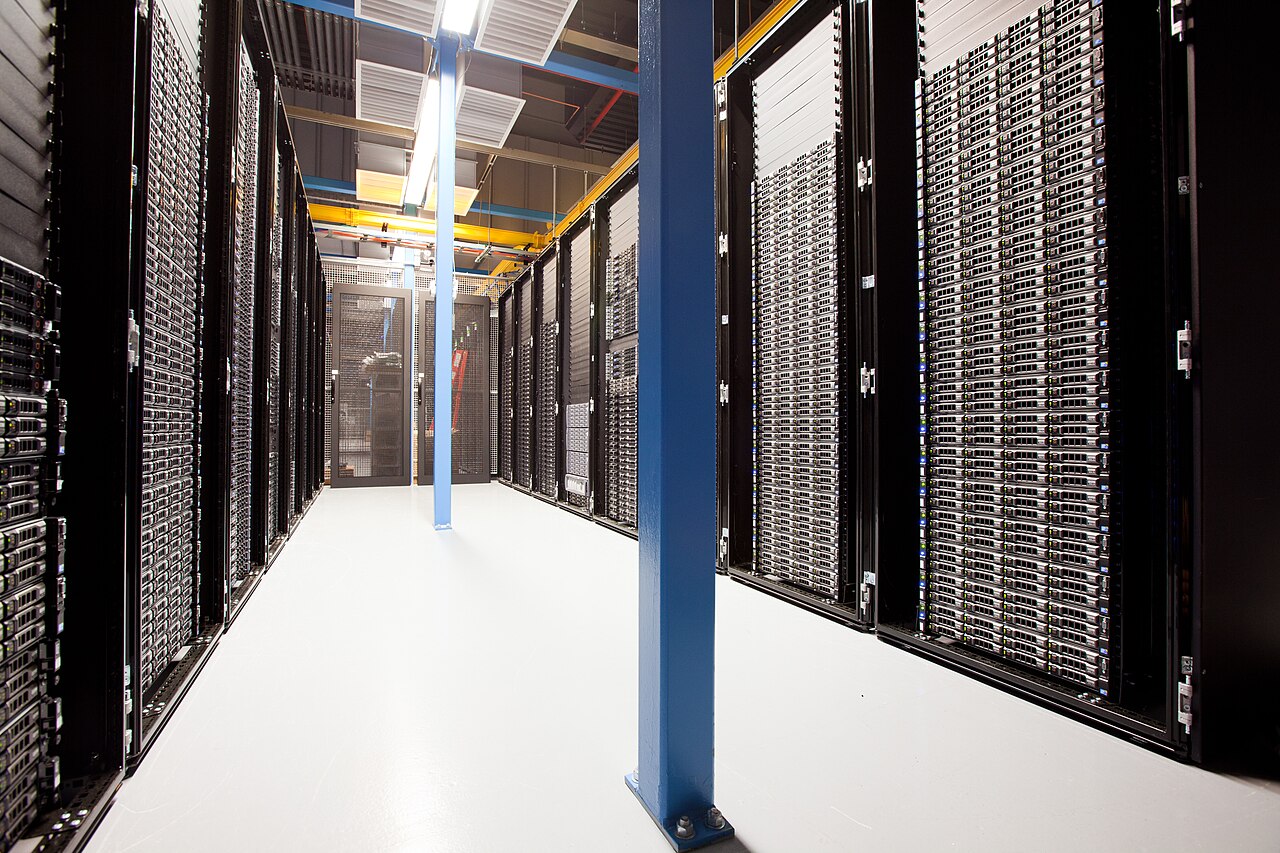
Yandex said a drone attack damaged its data center in Russia's Vladimir region on October 11, completely stopping operations at the facility and leaving some services unavailable. No injuries were reported. The shutdown was the third disruption to a major Yandex data center in four days, after the company's Sasovo site was taken offline and modules at its Kaluga facility were disabled.
The company's own Yandex Cloud Alerts channel described the remaining resource configuration as unstable and the platform as operating in emergency mode. Customers were told to activate alternative disaster-recovery plans, including external locations. Subsequent status updates showed a mixed picture: the cloud console and application-programming interface were available, compute was only partly available, some high-availability databases had failed over or become read-only, and object storage was readable but could have write problems.
The disruption reached beyond one machine room. Yandex Cloud listed outages or reduced availability across computing, storage, databases, Kubernetes, observability, security and AI services. Its October 11 update said key Yandex AI Studio model interfaces remained accessible, but retrieval, optical-character recognition, SpeechSense and AliceAI Pro were unavailable at that point. The company later said it was gradually restoring core services, without publishing a complete recovery schedule.
Reuters reported that the Vladimir incident followed strikes on October 8 at Sasovo, southeast of Moscow, and on October 9 at Kaluga, southwest of the capital. Yandex said the earlier Sasovo attack caused a fire and forced a suspension of operations. The site has housed tens of thousands of servers and two of the three supercomputers the company has used to develop its YandexGPT model. Yandex has not disclosed whether those supercomputers were damaged.
That distinction matters. Taking a building offline does not automatically mean AI training hardware has been destroyed, and available reports do not establish how much model-development capacity Yandex has lost. What is confirmed is operational concentration: multiple cloud zones, internal services and customer workloads relied on facilities that became unavailable in quick succession. Associated Press reporting said users in Russian cities and in Kazakhstan, Belarus and Armenia had problems accessing services including transport and payments.
The incident also demonstrates how the boundaries between consumer technology, enterprise cloud and AI infrastructure have blurred. The same physical estate can support search, mobility, shopping and communications while hosting databases, developer platforms and large computing clusters. A failure therefore does not stay inside an AI laboratory. It can interrupt customer applications and everyday transactions while also constraining the capacity used for model training or inference.
Cloud architecture normally limits this risk through availability zones, replicated data, independent power paths and recovery exercises. Those controls are designed to prevent a local equipment or utility failure from becoming a regional outage. They are less effective when several facilities within the same geography are disrupted in a short period, especially if clients have not maintained recoverable copies outside the provider's affected footprint. Yandex's recommendation to use alternative sites is a practical acknowledgement that redundancy inside one regional system may not be enough.
Kommersant reported late on October 11 that Yandex Cloud had arranged accelerated placement of customer data and services with other Russian providers, including Selectel, K2 Cloud and VK Cloud. It also reported that the Vladimir complex hosted another Yandex supercomputer, Galushkin. Those details raise a longer-term capacity question: high-end accelerators, networking equipment and power infrastructure cannot necessarily be replaced on the same timetable as ordinary servers, particularly in a constrained hardware market.
INNOVOX analysis: this is a warning for every operator building national or regional AI capacity. The critical asset is not just a model file. It is a system of accelerators, storage, networking, power, cooling, identity services and recovery controls. If too many of those components share a small number of physical sites, a provider can have nominal backups while retaining one large geographic failure domain. Resilience plans should test simultaneous site loss, preserve offline recovery paths and give customers evidence about where replicas actually live.
What to watch next is evidence, not speculation. Yandex has yet to quantify the physical damage, identify affected computing clusters or set full restoration dates. Recovery of the ru-central availability zones, clearer disclosure about the three supercomputers and the pace of customer migration will indicate whether the episode is a short service interruption or a lasting reduction in capacity. The wider industry question is whether operators respond by distributing compute more broadly, hardening sites or accepting higher costs for deeper redundancy.
INNOVOX analysis
The episode shows that AI resilience cannot be measured only in model quality or chip supply. Concentrated compute, power and cloud control planes create physical failure domains that can propagate into consumer services, business applications and model-development capacity at the same time.
What to watch
Watch Yandex's restoration timetable, disclosure of hardware damage, recovery of affected availability zones, customer migration to other providers and any redesign of redundancy or physical protection across the company's data-center fleet.